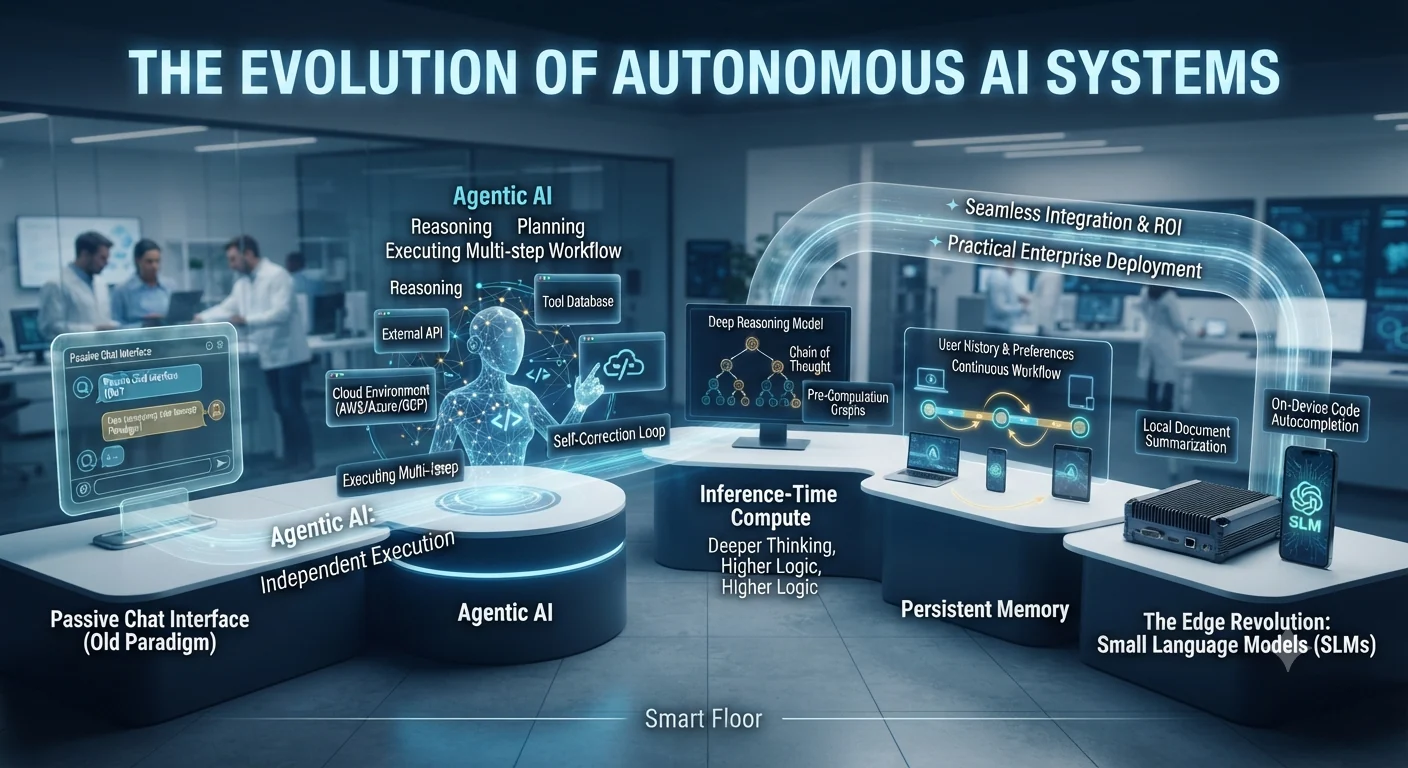
Autonomous AI is best examined as a set of system-design choices rather than an inevitable replacement for conversational software. An application may connect a model to tools, stored information and a sequence of actions. Another may need only a single response. The useful distinction is how work is coordinated, which decisions are delegated and how success or failure is established.
This article follows five related questions: how agents act, where additional computation can help, how state persists, when local models are suitable and how an organization might evaluate value. These are technical and operational considerations, not claims that all enterprises are adopting the same architecture. Research results, implementation experience and demonstrated business outcomes provide different kinds of evidence.
Agentic AI: Bounded Workflows and Actions
Agentic systems can be designed to plan tasks, retrieve information, invoke tools or APIs, execute bounded actions and evaluate intermediate results. Their autonomy depends on system design, permissions, available tools, safeguards, task complexity and human oversight. A request to complete a task is not itself proof that the system has the authority or ability to complete every step.
Anthropic's Building Effective Agents distinguishes predefined workflows from systems in which a model directs tool use dynamically. It discusses the trade-offs of adding agentic complexity, including cost, latency and the possibility of compounding errors. This is engineering guidance based on particular implementations, not a measurement of adoption across the whole industry.
For example, a support application could retrieve an order, propose a response and request human authorization for a consequential change. Evaluating intermediate results may expose an error, but a retry can also repeat or compound it. Useful boundaries include restricted tools, explicit stopping conditions and an escalation route. Task evaluation should examine both successful completion and inappropriate actions.
Longer workflows may increase token use through repeated calls, retrieved material and accumulated context. The effect depends on the architecture and workload: summaries, retrieval limits, caching and shorter interactions change what is processed. Measure completed-task cost and time rather than assuming that every agent uses a fixed multiple of a chat interaction.
Inference-Time Compute: Strategies and Limits
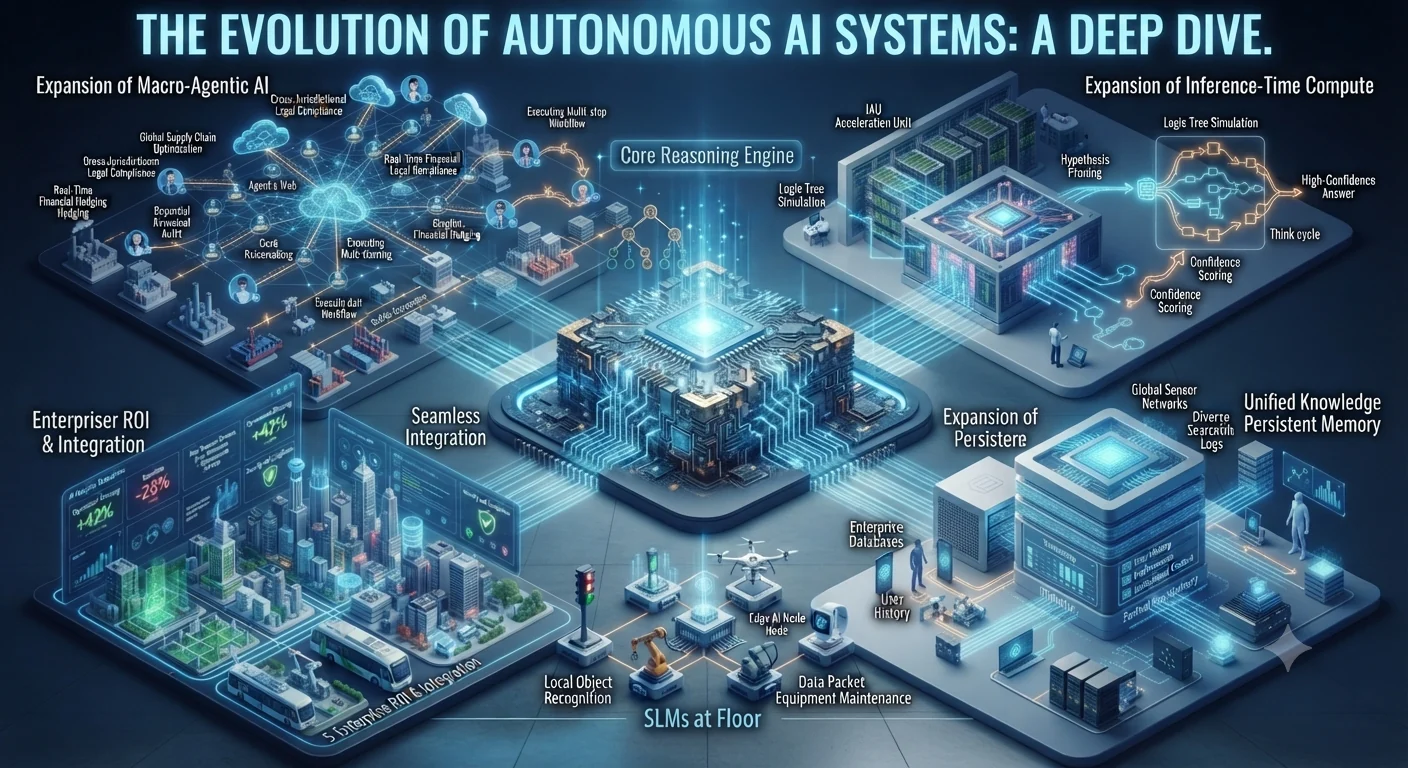
Inference-time, or test-time, compute refers here to resources used while producing or selecting an answer. Documented approaches include generating candidate answers, evaluating them with a verifier and refining proposals. These are research and application strategies; they do not establish that every reasoning model uses the same internal procedure.
The research paper Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters investigates allocating computation to improve reasoning performance. Its findings depend on the problem, model and strategy. Additional computation can help on some tasks under particular budgets; it is not a universal guarantee of correctness or a substitute for all training improvements.
There is no basis for assuming that every model secretly searches multiple paths, critiques each hypothesis or backtracks in the same way. Nor does application-level processing necessarily finish before any visible output: an application can interleave model responses, tool results and checks. Describing documented behavior is more useful than presenting an imagined hidden mechanism as fact.
A deployment evaluation should compare answer quality against elapsed time and compute cost on representative tasks. Extra attempts can consume a budget without finding a correct answer, and an evaluator can make mistakes. A longer response or reasoning trace should not be treated as evidence that a conclusion is reliable.
Persistent Memory and Continuous Workflows
Persistent memory is an application capability, not necessarily a change to a model's learned parameters. A system may store user preferences, retrieve records from a database, summarize prior interactions or maintain an external memory store and application state. Each mechanism determines what can be recovered in a later session.
Consider a project assistant that stores completed steps and unresolved questions. On resuming work, it could retrieve those records and compare them with the current project. This can support continuity across a long-running task, but it does not guarantee accurate recollection of every decision or dependable autonomous work over several weeks.
Stored information can become stale, a summary can omit an important condition and retrieval can select the wrong record. Context limits also determine how much recovered material is available for a particular response. Systems should distinguish recorded facts from inferred preferences and make corrections possible. Privacy controls, retention choices, access restrictions and a way to inspect or delete stored information matter as much as remembering more.
Small Language Models and Edge Deployment
A smaller language model may fit a local device or a constrained task more readily than a larger model, depending on its memory requirements and implementation. Model size alone does not establish usefulness. Hardware, numerical precision, context length, workload and the quality required for the task all affect the result. This discussion does not claim a particular share of market adoption.
Local execution can avoid a network round trip for the model request and may reduce the need to transmit sensitive inputs. Those are possible architectural advantages, not guarantees of faster execution or complete privacy. A slow device may take longer to answer; local logs, telemetry, retrieved services or cloud fallbacks can still move or expose information.
Security depends on device protection, software updates, permissions and data handling. Total cost includes hardware, energy, integration and maintenance as well as any hosted inference charges. A suitable comparison measures the actual workload under the intended operating conditions instead of declaring local models automatically safer, cheaper or more secure.
Offline use requires that the model and necessary data be available locally and that essential tools do not depend on remote services. A small model might be evaluated for document summarization or a narrow classification task, with clear handling of unsupported requests. Suitability for a regulated environment also depends on organizational controls and the specific requirements, not simply on where inference runs.
Model Choice and Enterprise Evaluation
Model commoditization is one interpretation of expanding technical options, not proof that models are interchangeable. Systems can differ in tool behavior, output formats, context handling, reliability and operating constraints. Replacing a model should prompt an evaluation of the complete workflow rather than an assumption that similar benchmark scores imply equivalent behavior.
Benchmarks provide evidence about the conditions they test. An enterprise also needs evidence from its own tasks, data and failure cases. For a proposed support workflow, useful measures might include correctly resolved requests, unnecessary escalations, review effort, response time and total operating cost. These are suggested evaluation criteria, not claimed results from an ASARK deployment.
A business case should compare the proposed system with a defined baseline over a stated period. Apparent time savings can be reduced by correction work, monitoring and integration costs. A successful demonstration is different from a sustained production result, and a technical research improvement is different from measured return on investment.
The practical direction depends on the job. Some applications may benefit from bounded agents; others may be better served by retrieval, fixed workflows or conventional software. The editorial conclusion is to match autonomy, memory and compute to observable needs, with sufficient evidence to decide whether the added complexity is worthwhile.
Return to AI Technology, explore Semiconductor Technology, or read the ASARK AI Technology Journal.
Sources & Further Reading
- Anthropic — Building Effective Agents: engineering patterns, evaluation and trade-offs in agentic systems; originally published December 19, 2024. Tooling examples may change over time.
- Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters: original research on test-time computation, with results bounded by the evaluated tasks and methods.
The memory, local-deployment and business-evaluation examples above describe design considerations. They are not market statistics, product endorsements or claims of demonstrated enterprise returns.